
APACHE CASSANDRA · INDEPENDENT ENGINEERING
Distributed Data at Operational Scale.
Design and manage Apache Cassandra deployments for workloads needing partition-aware data modeling, distribution and predictable operational behavior.
Independent Apache Cassandra engineering.
These are independent Bassirah engineering and support offerings. They do not imply upstream vendor or foundation endorsement, official vendor support rights, enterprise feature entitlement or maintenance guarantees.
Apache Cassandra and Apache are trademarks of The Apache Software Foundation.
WHY IT MATTERS
Built to Distribute. Engineered to Behave Predictably.
Cassandra requires careful partitioning, consistency policies, capacity planning and repair operations to meet service objectives.
Cassandra’s masterless design replicates data across nodes and datacenters, so the cluster can keep serving requests when individual nodes fail. That strength depends on getting the fundamentals right. Data models must follow query patterns, consistency levels must match business expectations, and repair, compaction and capacity must be operated continuously. Bassirah focuses on exactly those fundamentals.
WHAT BASSIRAH DELIVERS
Independent Cassandra Engineering and Operations
- Data modeling — Model access patterns and partition keys before deployment.
- Topology — Design multi-node and multi-datacenter topology and replication settings.
- Operations — Implement repair, backup, restore, monitoring and version lifecycle.
- Tuning and runbooks — Tune compaction, consistency, capacity and operational runbooks.
- Security — Client and internode encryption, authentication and role-based authorization.
- Capacity planning — Disk headroom for compaction, node density and growth planning before limits are reached.
- Upgrades — Rolling upgrades with compatibility checks for drivers, schema and tooling.
- Health reviews — Assessment of existing clusters: partition sizes, tombstones, repair status, latency outliers and configuration drift.
MODEL BEFORE YOU DEPLOY
In Cassandra, the Query Defines the Table
- List the queriesCapture every read and write the application performs, with expected volumes and latency objectives.
- Design tables per queryChoose partition and clustering keys so each query reads from as few partitions as possible.
- Bound partition sizeUse time buckets or other techniques so partitions do not grow without limit.
- Plan data lifecycleDefine TTLs, deletion patterns and compaction strategy together to keep tombstones under control.
TOPOLOGY
Replication and Consistency, Chosen Deliberately
We design datacenter-aware replication, rack placement and consistency levels so that a node, rack or datacenter failure has a known, tested recovery effect on availability and data correctness. Consistency is tuned per operation, not set once for the whole cluster.
| Decision | Typical approach | Trade-off we make explicit |
|---|---|---|
| Replication strategy | Datacenter-aware replication with replicas spread across racks or zones | Storage cost vs. tolerance of node and rack loss |
| Consistency per operation | Local-quorum reads and writes for most operations, stronger levels only where needed | Latency and availability vs. stronger cross-datacenter guarantees |
| Datacenter roles | Active in multiple datacenters, or a separate datacenter for analytics workloads | Isolation of analytical load vs. infrastructure cost |
| Failure response | Documented behavior for node, rack and datacenter loss | Tested recovery time vs. operational complexity |
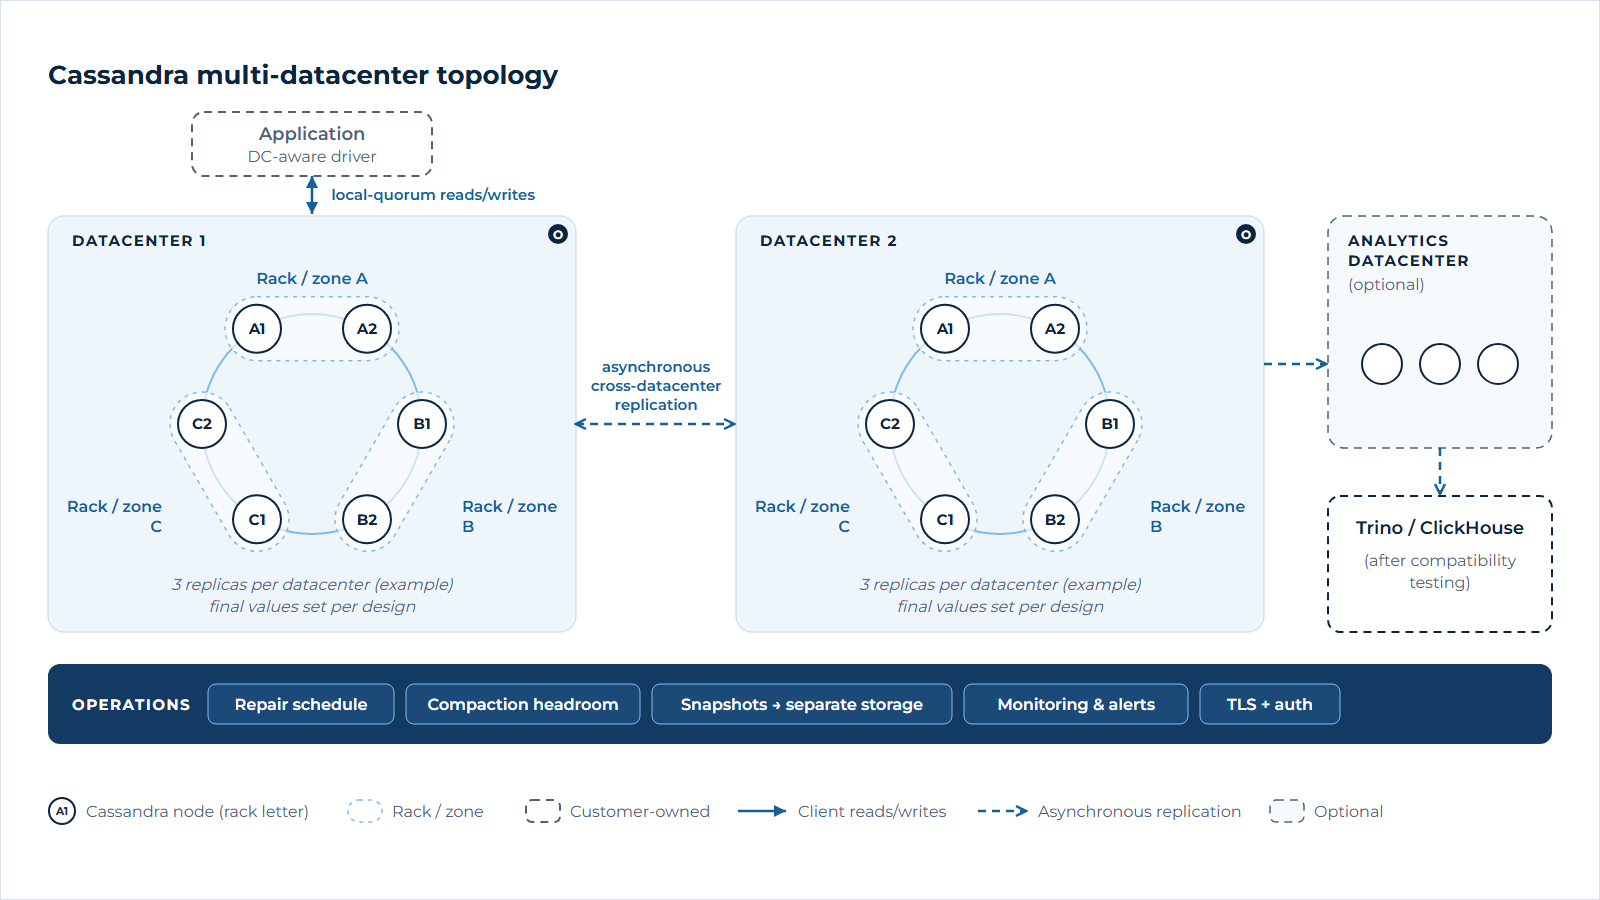
Cassandra multi-datacenter topology
OPERATIONS
The Routine Work That Prevents Incidents
Repair
Schedule and monitor anti-entropy repair so replicas stay consistent and deleted data does not reappear.
Compaction
Choose compaction strategy per table and keep disk headroom for compaction to run.
Backup and restore
Snapshot-based backups shipped to separate storage, with restore drills that prove recovery time.
Monitoring
Latency percentiles, pending compactions, dropped messages, disk use and repair status with actionable alerts.
Seeing latency spikes, tombstone warnings or repair backlogs?
We will review your cluster and prioritize fixes.
USE CASES
Where Cassandra Fits
High-ingest events
High-ingest operational events and time-series-like data patterns.
Geographically distributed data
Geographically distributed application data served close to users in each region.
Highly available services
Highly available services with carefully engineered consistency behavior.
WORKS WITH
Cassandra in the Wider Portfolio
Use Trino or Starburst connector paths only after compatibility testing. Redis and ClickHouse may complement application serving and analytics roles.
Trino OSS
SQL access to Cassandra data for analysis, after compatibility and load testing.
OSS
ClickHouse OSS
A dedicated analytical store for event history, keeping heavy analytics off the operational cluster.
OSS
Redis
Low-latency caching and application state where measurements justify it.
Strategic Partner
Managed Services
Contracted operations, repair management and incident handling for Cassandra estates.
Apache Cassandra: Frequently Asked Questions
Why does Cassandra need regular repair?
Replicas can diverge after node outages or dropped writes. Repair reconciles them. Running repair within the window your tombstone settings allow also prevents deleted data from reappearing.
Can Cassandra run across multiple datacenters?
Yes. Cassandra supports datacenter-aware replication. We design replication, consistency levels and failure behavior so the effect of losing a datacenter is known and tested against your recovery objectives.
Can we run analytics directly on Cassandra?
Cassandra is designed for known, partition-based access patterns. For broad analytics, we usually recommend querying through Trino after compatibility testing, or moving event history into an analytical store such as ClickHouse.
Do you provide official Apache Cassandra support?
Apache Cassandra is a community project of The Apache Software Foundation. Our services are independent engineering and support, with scope and response terms defined in your contract.
Can you take over an existing cluster we inherited?
Yes. We start with a health review of data models, configuration, repair and backup status, and capacity, then agree a remediation plan and ongoing support scope.
Make Distributed Data Predictable.
Tell us about your topology, workloads and service objectives. We will scope a resilience assessment and a practical next step.